pAIge
Synthetic Document Generation
Core Problem
LLMs hallucinate layout coordinates and text content when generating synthetic documents for OCR model training.
Role & Focus
ML Engineer
Technologies
Architecture & Background
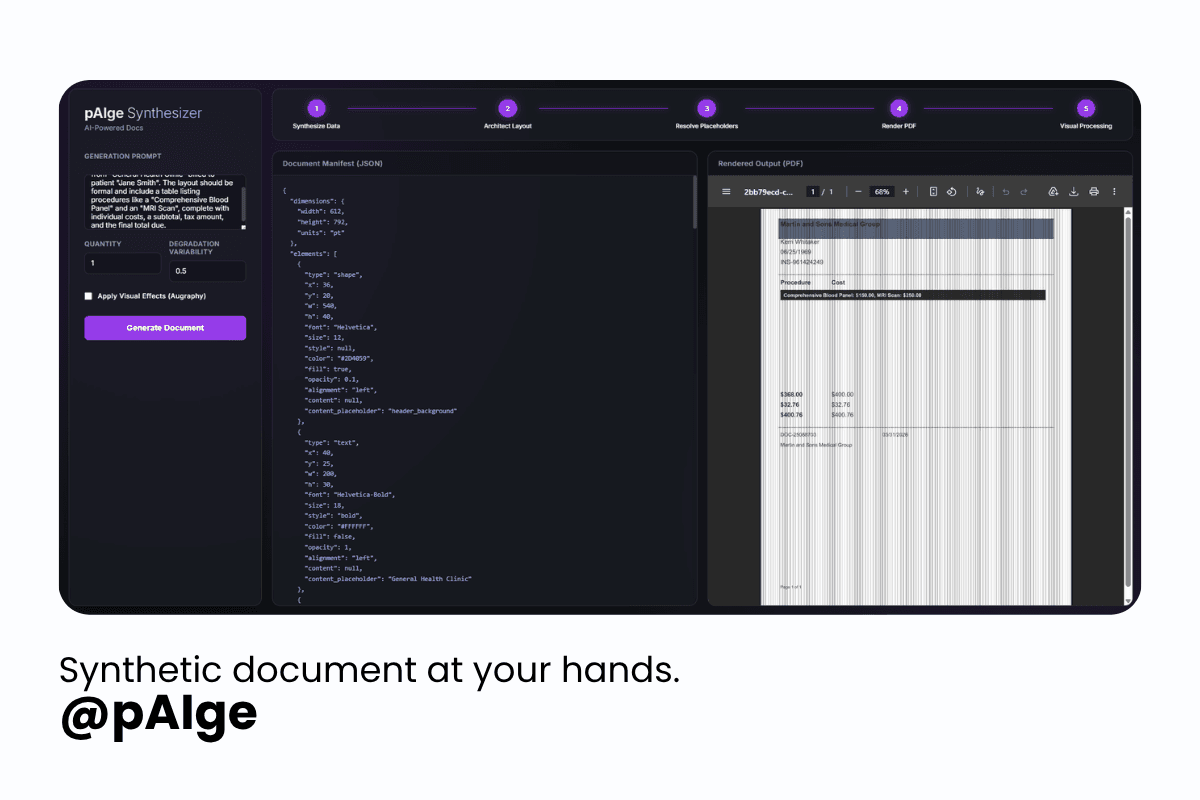
Architected a multi-stage synthetic document generation pipeline using LangChain, Groq, and Augraphy. Enforced a data-first Field Bank constraint pattern that completely eliminates LLM hallucination and generates production-grade OCR training data at scale.
Engineering Strategy
A 6-stage deterministic pipeline enforcing a strict Field Bank constraint before LLM inference, verified with 23+ automated tests.
Key Technical Implementations
Field Bank pattern—constrain LLMs to real data before generation
Multi-stage orchestration with LangChain
Groq + Cerebras for inference speed
Augraphy for visual degradation (realistic aging)